tokdump
Like hexdump, but for tokens — o200k_base, hexdump-C style.
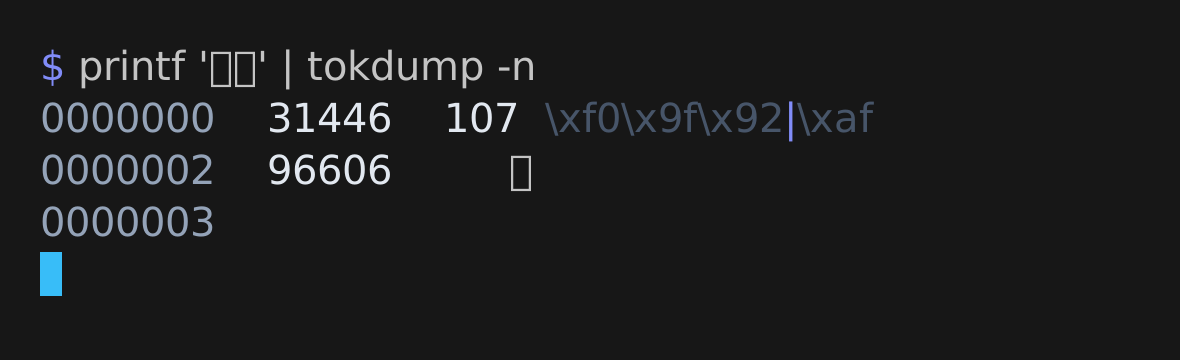
tokdump is hexdump for tokens. Point it at a file or pipe stdin and it dumps OpenAI o200k_base token IDs in a classic three-column hexdump-C layout — offset, IDs, and a text column that makes invisible Unicode visible.
What it does
Plain tokdump always means o200k_base (GPT-4o and friends). Each dump line is:
- Offset — token index as 7 lowercase hex digits
- Token IDs — 4 per row by default (2 with
-n/--narrow), width-7 right-aligned - Text column — decoded pieces separated by
|, with spaces as·, newlines as↵, and escapes for zero-width, bidi, and split-byte junk instead of blank glyphs
Decimal IDs by default; -x / --hex for hexadecimal. Multiple files get a tokdump: FILENAME: header before each dump.
Install
brew install omarish/tap/tokdump
Or grab a binary from GitHub Releases, or build with Go:
go install github.com/omarish/tokdump@latest
Usage
echo -n "Hello world" | tokdump
tokdump README.md
tokdump -x a.txt
tokdump -n a.txt
Source: github.com/omarish/tokdump